Prompt Injection Rises Above CVEs in LLM Security
A new analysis says prompt injection tops OWASP’s LLM risk list but sits far lower in incident data, highlighting a visibility gap that scanners miss.
Prompt injection is still the top risk on OWASP’s list for LLM applications, but a new analysis suggests the public incident record tells a different story. That split matters because it shows how an attack can be highly important to defenders even when it leaves little trace in traditional vulnerability tracking.
The analysis comes from Kyriakos “Rock” Lambros and Steve Wilson, two leaders of the OWASP Top 10 for LLM Applications project. They published the work on arXiv and made clear it is exploratory, not peer reviewed, and not the official OWASP release. In other words, it is a research signal rather than a final standards update.
Still, the numbers are substantial. The authors examined 7,714 LLM security incidents from sources including CVE, GitHub Security Advisories, OSV, and the AIAAIC AI-harm database. Of those, 6,639 were labeled against a 20-entry taxonomy. They then used a Bayesian model to adjust the counts for classifier error before comparing the incident-based ranking with the expert-driven OWASP ranking.
Prompt Injection And The Incident Gap
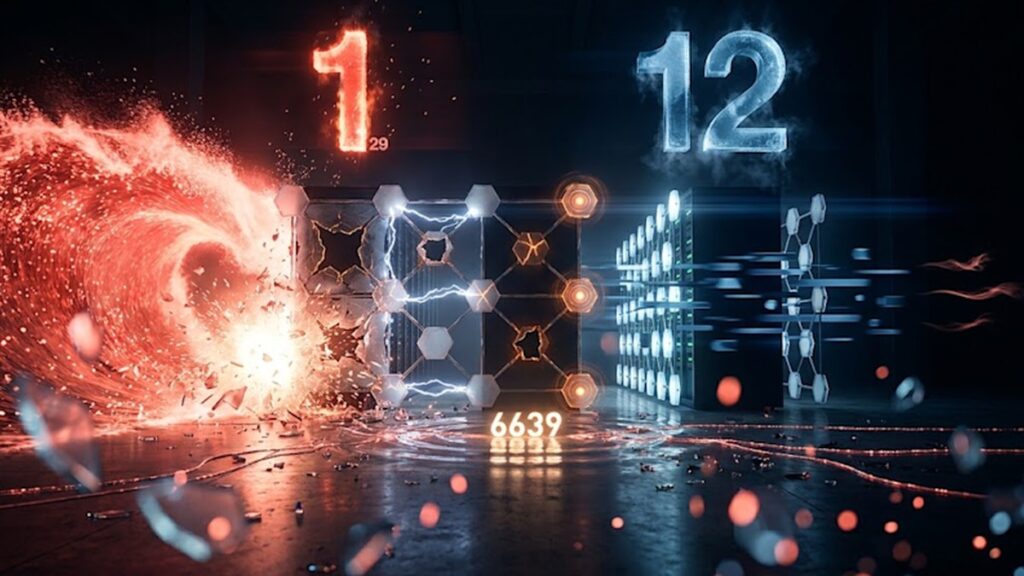
In that comparison, prompt injection ranked No. 1 in the OWASP Top 10 for LLM Applications, yet only No. 12 in the incident record. The authors say that does not mean the attack is harmless. Instead, it suggests a visibility problem: many real incidents will never appear in the datasets security teams use to count and compare threats.
The paper’s central point is that the attack works in places scanners do not inspect well. Prompt injection can hide instructions inside content a model reads, such as a log entry, support ticket, or retrieved document. The model may then take the tool action an attacker wanted while using credentials it already has. Because that chain does not necessarily map to a product flaw, it may not produce a CVE for a scanner to find.
That distinction is important for security teams. A low CVE count can make a threat look less urgent than it really is. But with LLM systems, absence from a scanner’s view is not the same thing as absence of risk. For organizations deploying copilots, agents, or retrieval-augmented systems, the attack surface includes the model’s inputs and the actions it is allowed to take, not just the software stack underneath.
What The Data Actually Shows
The authors also found no statistically detectable agreement between expert judgment and the public incident record. Their reported Cohen’s kappa was 0.20, with a 90% interval that crossed zero. Their conclusion was cautious: weak agreement, not confirmation.
That means the expert list and the incident data are not simply telling the same story from two angles. They may be capturing different kinds of risk, different reporting patterns, or different blind spots. Lambros summarized the issue in written remarks by saying the two measures disagree and neither should be treated as the full truth.
For readers, the practical implication is clear. OWASP’s ranking remains a useful guide to what knowledgeable practitioners believe matters most, but incident data can lag, undercount, or miss attacks that do not surface as conventional security records. Prompt injection sits at the center of that mismatch.
Why This Matters For Security Teams
Organizations should read the finding as a warning against overreliance on passive scanning. If an AI system can be steered by hostile content, then the defense has to focus on how the system behaves in practice.
- Test deployed systems with adversarial prompts and malicious retrieved content.
- Limit what tools and data the agent can reach.
- Treat model inputs as untrusted, even when they come from internal systems.
- Review workflows where the model can trigger actions using existing credentials.
The next thing to watch is whether additional field data and future OWASP work reinforce or change this gap between expert ranking and incident history. For now, the takeaway is not that prompt injection is overhyped. It is that the attack is often invisible to the very measurement tools many teams use to decide what deserves attention first.