Nvidia’s AI Advantage Moves Beyond the GPU
Nvidia’s latest data center systems show how AI infrastructure is shifting from raw GPU power to orchestration, memory handling, and smarter traffic control.
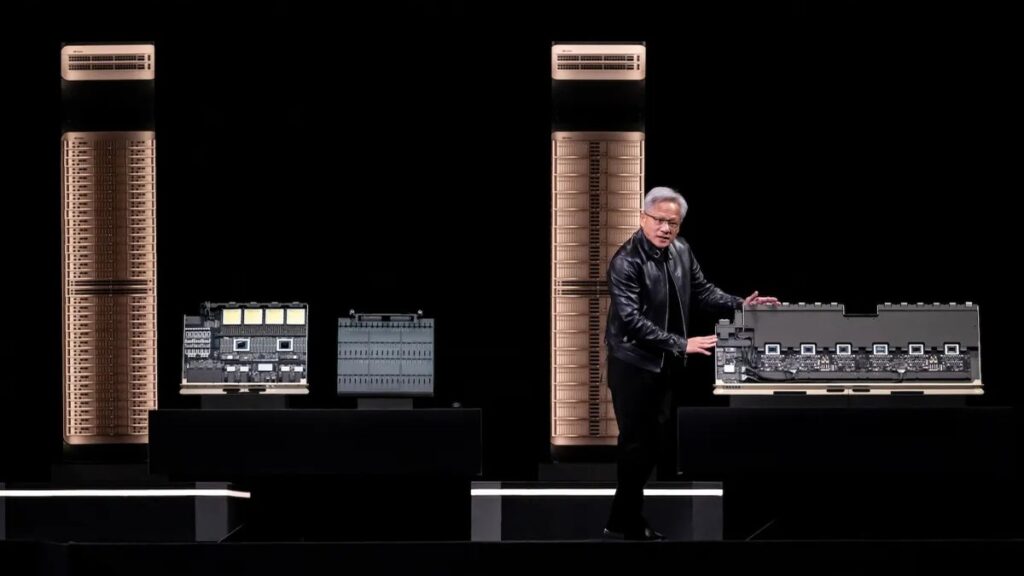
Nvidia’s AI story is no longer only about the GPU. The company still depends on its graphics processors as the core of its AI business, but the latest wave of data center systems suggests its advantage is moving beyond the GPU into the hardware and software that keep massive AI clusters running efficiently.
That shift matters because the AI infrastructure market has changed. Hyperscalers such as Amazon and Google have spent years building their own chips, so Nvidia is no longer the only major option for state-of-the-art AI compute. At the same time, the economics of AI are getting harder to ignore: as deployments grow larger, operators care less about raw throughput alone and more about how much useful work they can get from every watt, server, and memory hop.
Nvidia’s recent earnings helped sharpen that new narrative. Investors who had been focused on GPU competition are starting to pay more attention to the systems surrounding the GPU, where Nvidia still appears to have a strong position. The company’s strategy is not just to sell chips that generate tokens, but to sell the infrastructure that helps move data to those chips, keep workloads flowing, and reduce bottlenecks across very large deployments.
Why Beyond the GPU Matters
At the scale of modern AI data centers, compute is only part of the problem. The bigger challenge is orchestration: getting the right data to the right place at the right time, without wasting memory bandwidth or creating delays that slow the entire system.
Nvidia is rolling out its Vera Rubin architecture, which pairs the Rubin GPU with other components including the Vera CPU, along with racks for storage and networking. The important point is not only that these pieces exist, but that they are designed to work together as a system. In Nvidia’s framing, the GPU is the engine, while the surrounding hardware acts like the rest of the car.
Jason Hardy, Nvidia’s VP of storage technology, said Vera is important because memory capacity is limited in any single server or compute platform. As AI systems scale, more memory is needed, but simply adding memory does not solve the problem if data cannot be delivered efficiently. That is where traffic direction becomes valuable.
Hardy said Nvidia saw as much as a 3x improvement in certain operations when the Vera CPU was used for acceleration. He described this as helping the company use flash storage more fully by avoiding bottlenecks. For operators, that kind of improvement can translate into better efficiency and lower cost per unit of AI work.
Smarter Traffic Control Over Raw Power
The trend is not unique to Nvidia. OpenAI has also emphasized reducing data movement in its own chip work. The company said its Jalapeño chip was designed to minimize communication delays by keeping a large share of the workload inside one connected system. The goal is to keep requests fast and efficient by limiting the need to move data around.
That approach differs from Nvidia’s modular system design, but the principle is similar. Both are trying to improve performance by reducing wasted motion, not simply by adding more processor cycles. In practice, that means AI infrastructure is becoming a competition over orchestration, memory, storage, networking, and interconnects as much as over the main compute chip itself.
For buyers, this is an important change. The companies deploying AI at scale are no longer choosing only between chips. They are choosing among full systems, each with different tradeoffs in efficiency, flexibility, and total throughput. A platform that can move data better may deliver more useful compute even if its raw chip specs are not dramatically ahead.
What Investors And Buyers Should Watch
For investors, Nvidia’s latest story suggests its moat may be broader than the GPU market alone. If the company can keep leading in the systems that surround the GPU, it can remain central even as rivals catch up on standalone accelerators. The key question is whether Nvidia can keep translating that systems advantage into real-world performance gains for large customers.
For buyers, the practical implication is that future AI purchases may be judged increasingly by efficiency metrics such as tokens per watt, storage utilization, and how effectively data can be routed through a cluster. The best system may be the one that moves information with the least friction.
The next thing to watch is whether this systems-first framing becomes a larger part of how Nvidia presents its platform, and whether competitors respond by focusing more aggressively on data movement and orchestration. If the AI race is shifting beyond the GPU, then the next phase of competition may be won in the plumbing of the data center rather than only in the chip design itself.