TOTVS Rethinks Data Architecture For AI Agents
Fabiane Nardon explains how TOTVS is preparing enterprise data for AI agents by combining deterministic systems, semantic models, and MCP-based tool selection.
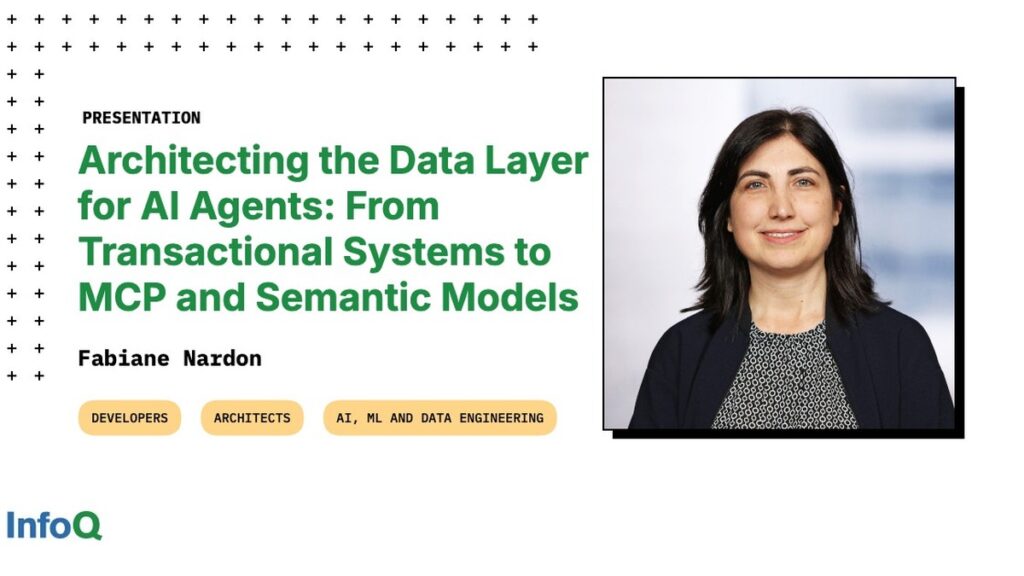
Enterprise teams are starting to face a new question: how should data architecture for AI agents change when software must serve both traditional transactional systems and large language model-driven workflows? In a recent InfoQ presentation, Fabiane Nardon described how TOTVS is approaching that problem by rethinking the data layer around precision, security, cost, and context efficiency.
The core challenge is that AI agents are not just another frontend. They can be token-hungry, they may ask for different information paths depending on the prompt, and they operate with non-deterministic behavior. That makes the data layer more than a storage concern. It becomes part of how the organization controls what an agent can see, how quickly it can access it, and how much context it needs to perform a task.
Nardon’s talk focuses on a practical enterprise reality: many systems were built for predictable application logic, not for agents that may need to combine search, retrieval, reasoning, and tool use. The result is a need to balance deterministic logic, which supports reliability and governance, with LLM-based workflows, which support flexibility and interaction.
Data Architecture For AI Agents In Enterprise Systems
At the center of this data architecture for AI agents discussion is the pressure to deliver useful responses without flooding the model with unnecessary context. Nardon highlighted the role of low-latency database architectures, semantic ontologies, and dynamic MCP tool selection as ways to keep agent interactions efficient inside transactional environments.
That matters because every extra piece of context has a cost. More tokens can mean more latency and higher expense, especially when an agent is calling into enterprise systems repeatedly. By shaping the data layer to provide narrower, more relevant context windows, organizations can reduce overhead while still giving agents enough information to complete a task.
Semantic models are important here because they help systems represent business meaning rather than only table structures or application-specific fields. In practice, that can make it easier for an agent to identify the right data source, understand relationships across domains, and avoid pulling in irrelevant records.
Nardon also pointed to data mesh as part of the architecture strategy. In this context, the value is not just decentralization for its own sake. It is about organizing data so that domains can expose more usable, governed data products that agents and tools can consume with less friction.
Why Precision Security And Cost Must Be Balanced
A major theme of the presentation is that data architecture for AI agents cannot optimize for speed alone. Enterprise systems still have to protect sensitive data, preserve precision, and keep costs in check. That means AI adoption cannot simply copy consumer chatbot patterns into production business workflows.
Deterministic logic remains important for anything that needs strict correctness. Non-deterministic LLMs can add value when tasks require interpretation, summarization, or flexible orchestration, but they also introduce uncertainty. TOTVS’s approach, as described by Nardon, is to use the strengths of each side where they fit best rather than letting the model handle everything.
This has practical implications for architecture teams. Security controls need to be built into the data pathways that agents use. Access boundaries matter because agents can act across tools and domains. Cost controls matter because inefficient retrieval or oversized prompts can make an otherwise promising use case expensive to run at scale.
The talk suggests that the right architecture is less about choosing between databases and models, and more about designing the handoff between them. The better that handoff works, the less the model has to guess, and the more reliably enterprise systems can support AI-driven tasks.
What Architects Should Watch Next
For architects, the practical takeaway is that AI agent readiness starts with the data layer, not the prompt layer. If the underlying systems are noisy, overly broad, or difficult to access safely, agents will inherit those weaknesses. If the data layer is shaped for relevance and governance, agents can operate with less wasted context and better control.
The next things to watch are how organizations apply MCP tool selection in production, how semantic ontologies are mapped to real business domains, and how low-latency design affects user experience when agents are working inside transactional workflows. These choices will shape whether AI agents become a useful enterprise capability or another layer of complexity.
Nardon’s presentation frames a clear message: successful AI agents depend on disciplined data architecture for AI agents. Enterprises that align data modeling, governance, and tool access around that reality will be better positioned to keep systems accurate, secure, and economically sustainable.